Reuse the foundation
How might different GenAI projects configure one evaluation system instead of rebuilding it?
It checks AI answers, then checks the checker.
A score from an AI judge looks precise and can still be wrong. Soteria checks AI answers for RAG, entity extraction and structured extraction, keeps the quote behind every judgement, and tests whether its own judges deserve trust. When it can't tell, it says so and hands the case to a person.
How might different GenAI projects configure one evaluation system instead of rebuilding it?
How might a score show the uncertainty and missing evidence behind it?
How might we evaluate the reliability of the evaluators themselves?
A judge’s answer can shift with prompt wording, input order, verbosity, style or model choice.
Evaluator reliability also has to be evaluated. A score alone is not enough.
Failures matter differently depending on risk.
Missing evidence must not quietly become a confident negative result.
A judge can be unstable even when the answer has not changed.
A change in scores does not by itself prove a change in the system.
Every judge question is asked three ways, and checked again under small changes to the input. Soteria grades its judges A to D from the weakest of those checks, not the average. With one judge model the grade stops at B, because one model can't show its own bias.
Stability 0.99 on one metric and 0.835 on another. Grade B: the weaker one decides.

You list the facts an answer must contain and how much each one matters, from Low (1) to Critical (5). The judges check each fact and quote the answer as proof. If they disagree, the fact is marked inconclusive and goes to a person instead of counting as a miss.
Required: notice at least 60 days before term end. The answer: "giving 30 days notice". Contradicted, Critical, weight 5.

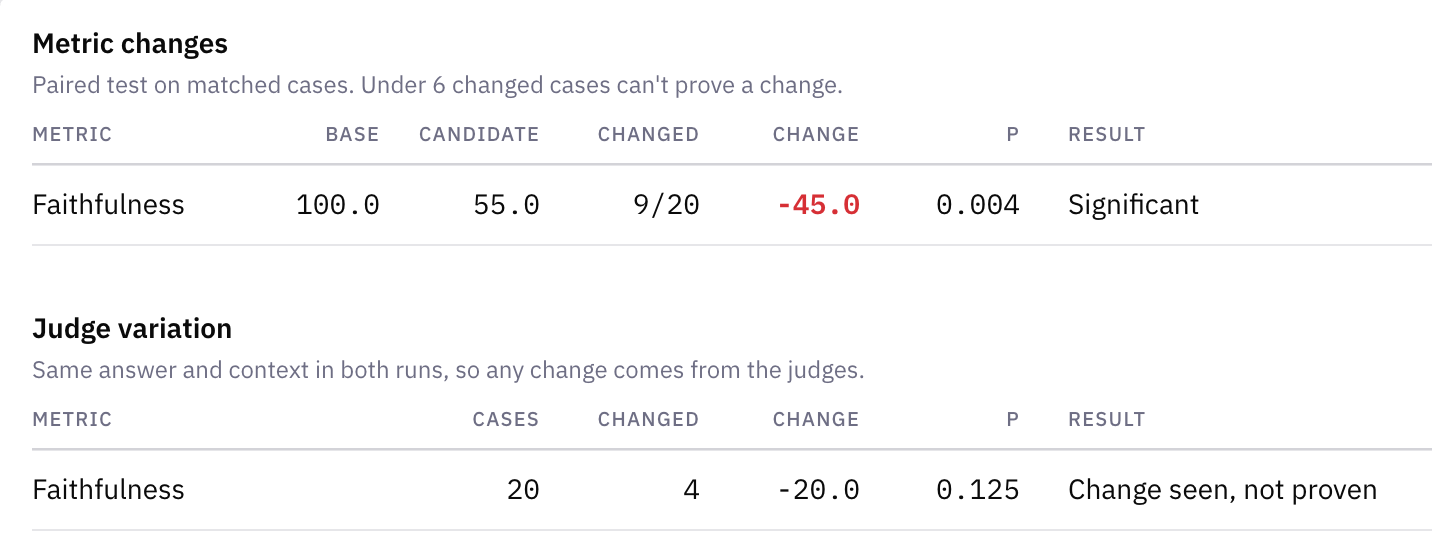
Soteria compares a run with an earlier one, case by case, and tests whether a drop is real. If the answers and context didn't change but the scores did, it counts that as the judge moving, not the system.
4 of 20 scores drop from 1 to 0. p = 0.125. Change seen, not proven. No alert.
The same evidence opens three ways. Business gets the consequence and what to do next. Engineers get the case to investigate. Auditors get the quote and the decision record.


